Put AI to work.
Stop counting tokens.

  • Private AI workers for long-running autonomous tasks
  • Predictable pricing — pay for work, not thoughts
up to 1M context
zero data retention
per-second billing
no token meter
Smart. Fast. Cheap.
A dedicated server standing alone on its own island, whales circling freely around it
Your workers run on dedicated infrastructure: only your work ever touches it.

Tell it what to do. Get work back.

1

Objective

Describe the outcome: fix the bug, upgrade the dependency, review the repo, build the feature.

→
2

noTOKEN worker

Plans, acts, verifies — on dedicated private infrastructure, for as long as the job takes.

→
3

Result

Completed work with a predictable cost. Tests passing, PR ready, review done.

Cloud AI charges for thinking. noTOKEN charges for working.

Intelligence good enough to do the job. Cheap enough to use everywhere.

Your agent is a whale. Per-token pricing is built for sardines.

Here's the story every heavy agent user lives — and the math that decides who wins.

1

Your agent re-reads everything, every turn.

A coding agent doesn't send a short question. It sends the whole conversation, the whole file, the whole plan — again, on every single turn. One prompt into an existing conversation at 1M context is already more than 100,000 input tokens. Ten turns an hour is a million tokens an hour. A serious setup — several agents, long horizons, big repos — runs 10 million tokens an hour, all day, every day.

2

Per-token APIs bill that whale at sardine prices… per sardine.

At 10M input tokens an hour, GLM-5.2's meter reads $14/hr. Kimi K3 reads $30/hr. And that's before output. The more your agent works, the more you pay — linearly, forever. The per-token model was built for people who ask one question and walk away. It is the exact opposite of what you are.

3

On a dedicated endpoint, the tokens are free.

You pay for the hour, not the tokens. 10M tokens an hour? 100M? 1 billion tokens an hour, per user, and that's fine. The meter doesn't care. Your server runs only your traffic, with up to 1M of context — and the price is the same whether your agent is idle or overflowing it. Heavy use is not a penalty here. It's the point.

4

And nothing you send is kept.

Your endpoint is dedicated to you. Your prompts, your code, your context — zero data retention. No training on your work, no logs of your conversations, no shared anything. The server is yours for the hour; when it stops, it's gone.

Your own lane. The whale swims alone — that's the whole product.
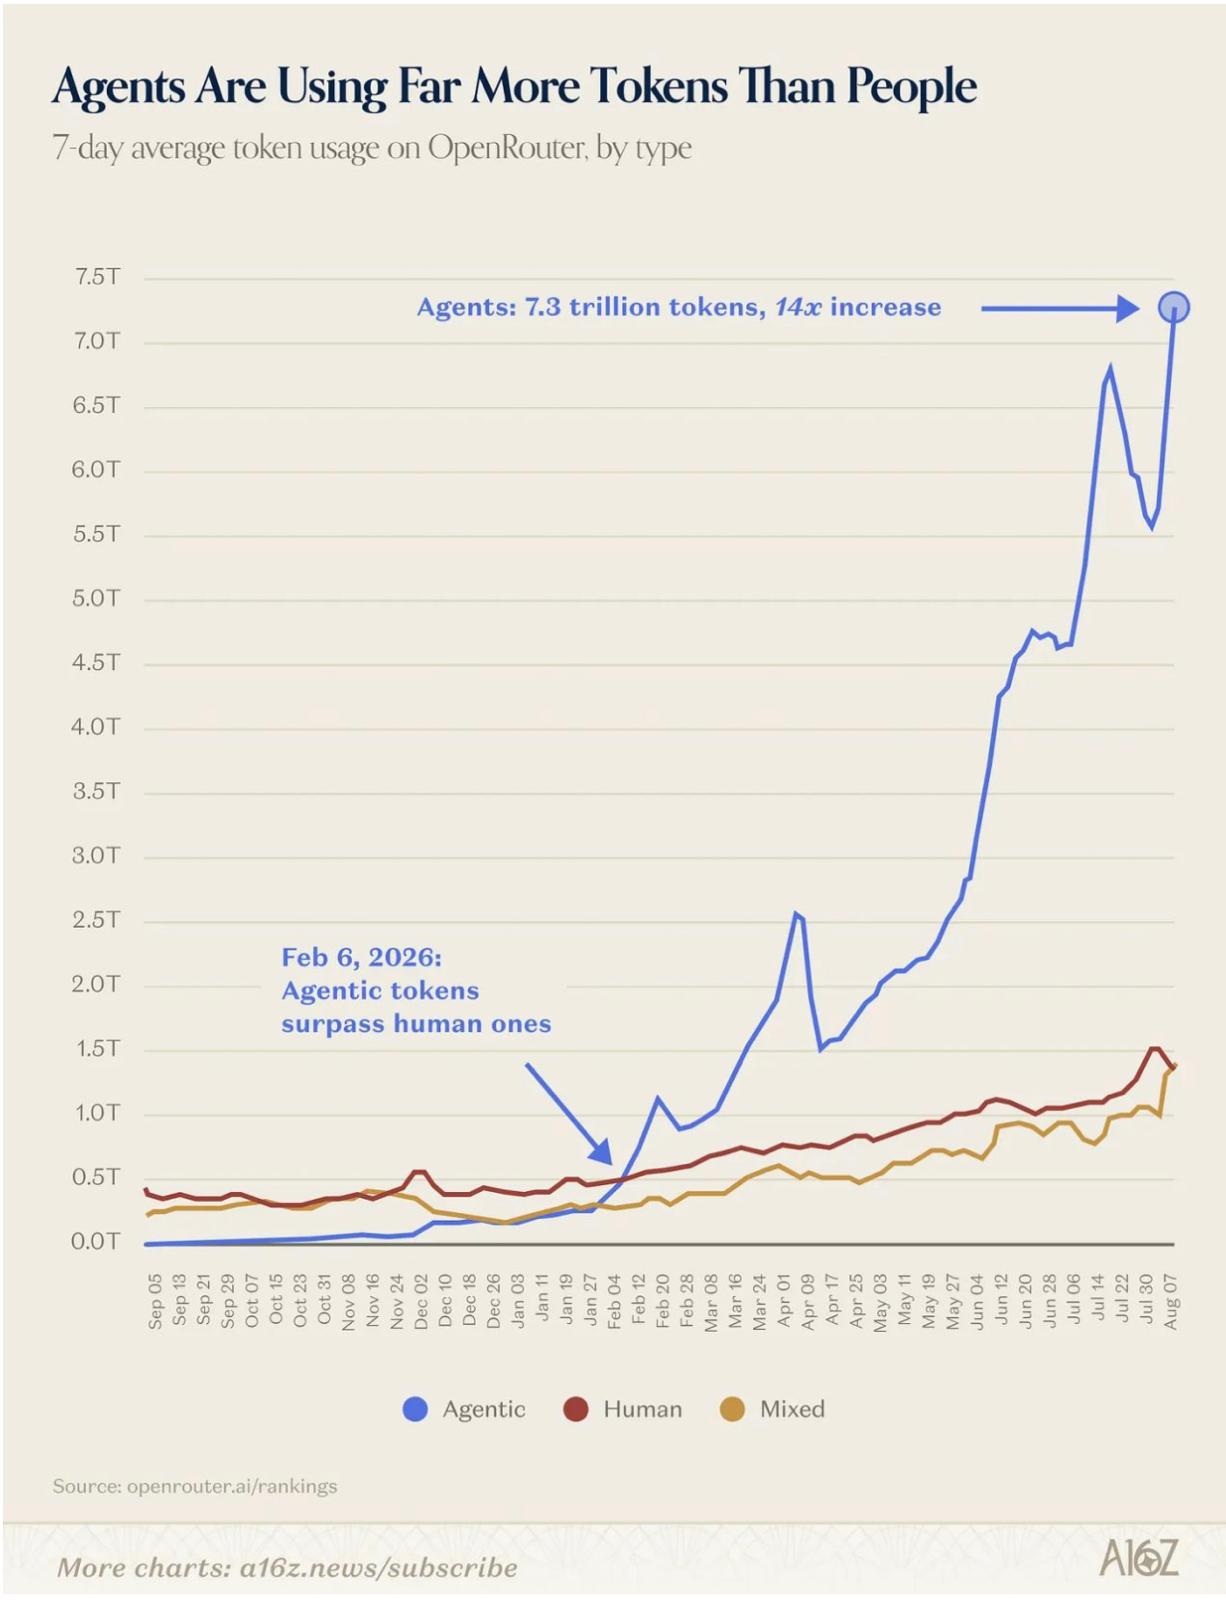
Agents now burn 7.3 trillion tokens a week on OpenRouter — 14× in a year. This is the whale. We priced for it. Source: a16z / openrouter.ai
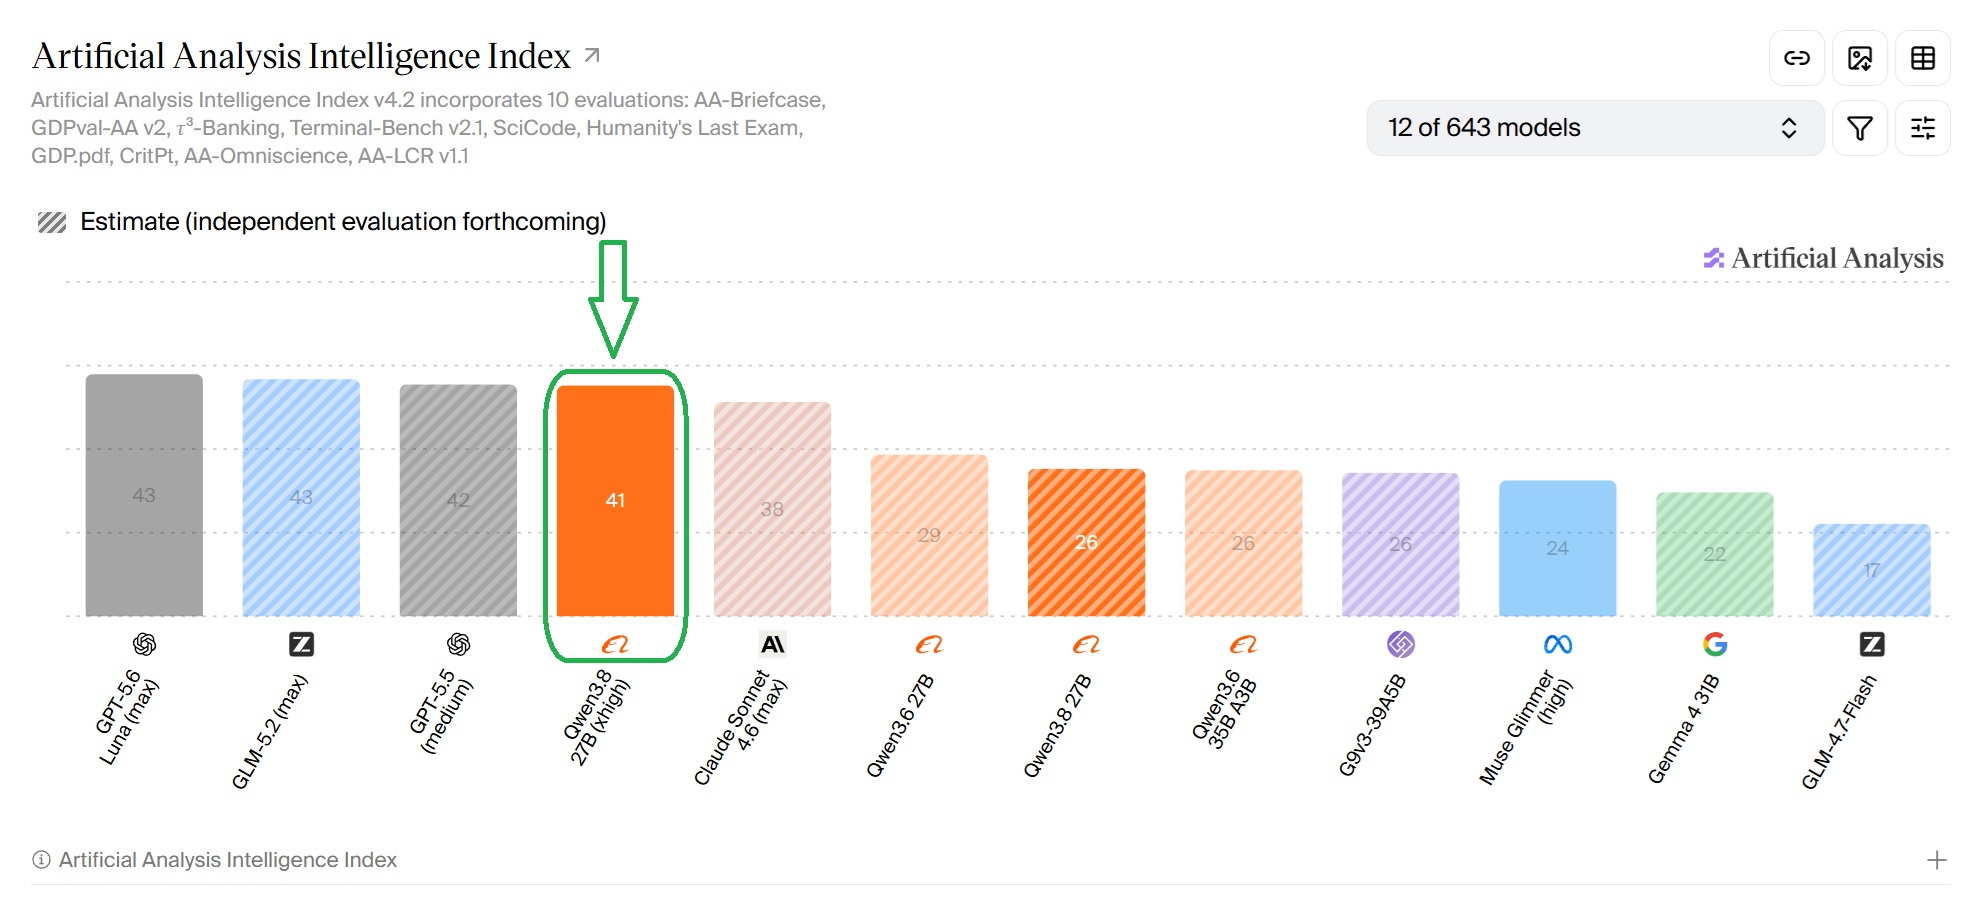
Artificial Analysis Intelligence Index v4.2: Qwen3.8-27B (xhigh) scores alongside GLM-5.2, GPT-5.5, and GPT-5.6 Luna
Qwen3.8-27B (xhigh), the version noTOKEN uses, scores alongside GLM-5.2, GPT-5.5, and GPT-5.6 Luna on the Artificial Analysis Intelligence Index v4.2. Source: artificialanalysis.ai

Pricing

Prepaid compute. $10 minimum. Your server auto-stops after your configured idle time (default 60 min, you can change it) and when credits run out — you only pay while your agent works. A new server takes up to 10 minutes to deploy. Per-second billing, no egress fees.

"Concurrent users" = concurrent in-flight generations (max-num-seqs), not unique humans. You get a dedicated server: zero data retention, auto-stop, per-second billing. *Starter Ada 1M ctx uses TNT SubQ — lossless up to 90K tokens, then a quality/speed tradeoff until 1M. All Blackwell configs use YaRN (Qwen's recommended method) — full attention to 100% of the context window, even at 1M.

Your first worker is waiting.

Card in, worker up, agent pointed. From $0.69/hr — you only pay while it works.

Start now — from $10

Connect your agent. 3 lines.

Your workers speak the language every coding tool already understands. Swap the base URL, paste your key, done.

1

Add credits

$10 minimum, prepaid. No subscription, no invoice cycle.

2

Pick your server

Three tiers from $0.69/hr. Change your mind later — it's hourly.

3

Wait for live — then plug in

Up to 10 minutes to deploy. Point your agent at the endpoint and go.

curl

curl https://api.notoken.cloud/{instance_id}/v1/chat/completions \
  -H "Authorization: Bearer $TNT_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"qwen3.8-27b","messages":[{"role":"user","content":"Hello"}]}'

Claude Code / Cline / Cursor / Aider / OpenCode

base_url:  https://api.notoken.cloud/{instance_id}/v1
api_key:   tnt-...          (from your dashboard)
model:     qwen3.8-27b

Your instance_id appears in the dashboard once the server is live. API keys label your tasks (see what each key is doing in the dashboard). They don't limit concurrency — that's your product's max-num-seqs.

Every server ships with

Qwen3.8-27B, ready to go

Every server ships already loaded with Qwen3.8-27B — tuned and optimized, no setup on your side. Launch it and it is live in minutes.

Auto-stop, your rules

Your server stops after your configured idle time (default 60 min — you can change it in the dashboard) or when credits hit zero (60s grace, in-flight generation finishes). New servers take up to 10 minutes to deploy. You pay only while it works.

AI-first support, human backup

AI answers in seconds, on this site and in your dashboard. Anything it can't resolve goes to a human engineer — [email protected].

Everything's included. Start now.

Auto-stop, AI support, per-second billing — all on every server, no add-ons.

Start now — from $10
🚧 Soon — pre-launch

Never miss a phone call again.

An AI receptionist for dentists, doctors, restaurants and every business where the phone rings while everyone works. It answers every call, books appointments, answers the usual questions, and transfers to your team when they're free. Inbound only — we don't do outbound campaigns.

1

Patient calls

Your line rings — answered in two rings, every time, even at peak hours and after closing.

→
2

AI receptionist

Books, reschedules and cancels appointments. Answers hours, address, insurance and pricing questions. Transfers to your team when they're available.

→
3

After hours

Appointment-capture voicemail: name, number, preferred time — transcribed and queued for you. A lead, not a lost call.

Practice

Dedicated GPU · 10 simultaneous calls

8h · Mon–Fri$499/mo
12h · Mon–Fri$599/mo
24/7$1,499/mo

Ultra

Dedicated GPU · 50 simultaneous calls

8h · Mon–Fri$999/mo
12h · Mon–Fri$1,299/mo
24/7$4,999/mo

Unlimited calls — the ceiling is physics, not a bill: 10 (or 50) people at once. You bring your own Twilio account for the phone number, speech and text — we run the AI brain on a dedicated GPU, only during the hours you choose.

Pre-launch: join the list and get your first month 50% off when we open.

Frequently asked questions

The questions everyone asks before putting AI to work.

Why would I pay for Qwen3.8 if it's open source?

The model is open source — the optimal configuration is not. Quantization, KV cache sizing, context scaling, GPU selection and tuning are where the speed lives. With noTOKEN you get the best possible speed and config, ready to use, in about 5 minutes. Time is money.

Why is the 260K-context Starter more expensive than the 1M one?

Because they are different classes of endpoint, not bigger/smaller versions of the same thing. The 1M Starter runs a private TNT llama.cpp fork with TNT-SWA attention: a 90K sliding window that keeps the KV cache small and cheap, which is how a 1M context fits at $0.69/hr. Up to 90K tokens it behaves exactly like Qwen's original full attention; beyond that, the sliding window trades a little quality for a giant, affordable context. The 260K Starter (and every Blackwell server) runs Qwen's original full attention — full quality at every context size, on faster hardware. Pick SWA when you want the biggest window for the money; pick full attention when you want maximum fidelity.

Is it the same as running Qwen on my own GPU?

Not really. Agentic workflows run 24/7 — your GPU depends on hardware, electricity, cooling and maintenance. noTOKEN gives you the hardware, continuity, best practices and a stable endpoint out of the box, 24/7, so you can focus only on your agentic tasks.

Why not just use Claude or ChatGPT?

Claude and ChatGPT are incredible tools for frontier intelligence — and for general-purpose work their tools are equal to or worse than Qwen3.8. But when you need to run 300 AI agents 24/7 on long-horizon, repetitive tasks, you don't want a token-based meter running. We give you stable, immutable endpoints that only you use — the tokens are free, the hour is flat.

What if a lot of users join and speeds go down?

We sell dedicated GPUs, not a shared environment. Our goal is to see 100% of our clients using 100% of their GPUs, 100% of the time. Everyone can — and must — run their endpoint at full capacity. That's what a dedicated GPU service is for.

Can I reserve capacity for longer periods, or bigger GPUs like B200/B300?

Yes. We're prepared to supply long-term agreements with higher-capacity GPUs. Reach out to us at [email protected].

Can I own the model weights that I am using on notoken.cloud?

Yes. The weights used on notoken.cloud servers — MXFP4 and the BF16 mmproj — can be downloaded from our Hugging Face page. The repo also includes Q3Q4/Q2Q4 GGUF variants for running locally. All at https://huggingface.co/cafepm/Qwen3.8-27B-Q3Q4-GGUF.

The noTOKEN.cloud newsletter

New SKUs, new model drops, pricing changes, and the occasional benchmark we're proud of. No spam — unsubscribe anytime.